
More project photos (2)
The problem
Air pollution now shapes daily routines in Indian cities — school advisories, construction pauses and health warnings all hinge on the Air Quality Index. The Central Pollution Control Board publishes the National Air Quality Index, computed from pollutant sub-indices through a fixed breakpoint table, and streams station-level measurements through its portal alongside the global OpenAQ archive. But raw concentrations do not tell a citizen what to do, and advisories usually arrive after the smog does. Predicting the next hours' AQI from current station readings is a tabular time-series regression problem, and Random Forest handles it well: pollutant chemistry and dispersion are strongly non-linear, and forests tolerate the occasional sensor gaps real feeds contain. This project builds that forecaster end to end — ingestion, lagged features, per-pollutant forests, exact CPCB AQI math, and a dashboard with health advisories.
How it works
- The scheduler polls CPCB/OpenAQ station feeds hourly; each record passes range validation, short gaps are linearly interpolated, and longer gaps are marked missing.
- The feature builder materialises lagged pollutant levels (1/3/6/24 h), meteorological readings and calendar features into the training table.
- One RandomForestRegressor per pollutant trains on the historical feature table to predict next-hour concentrations; forests are used because dispersion chemistry is non-linear.
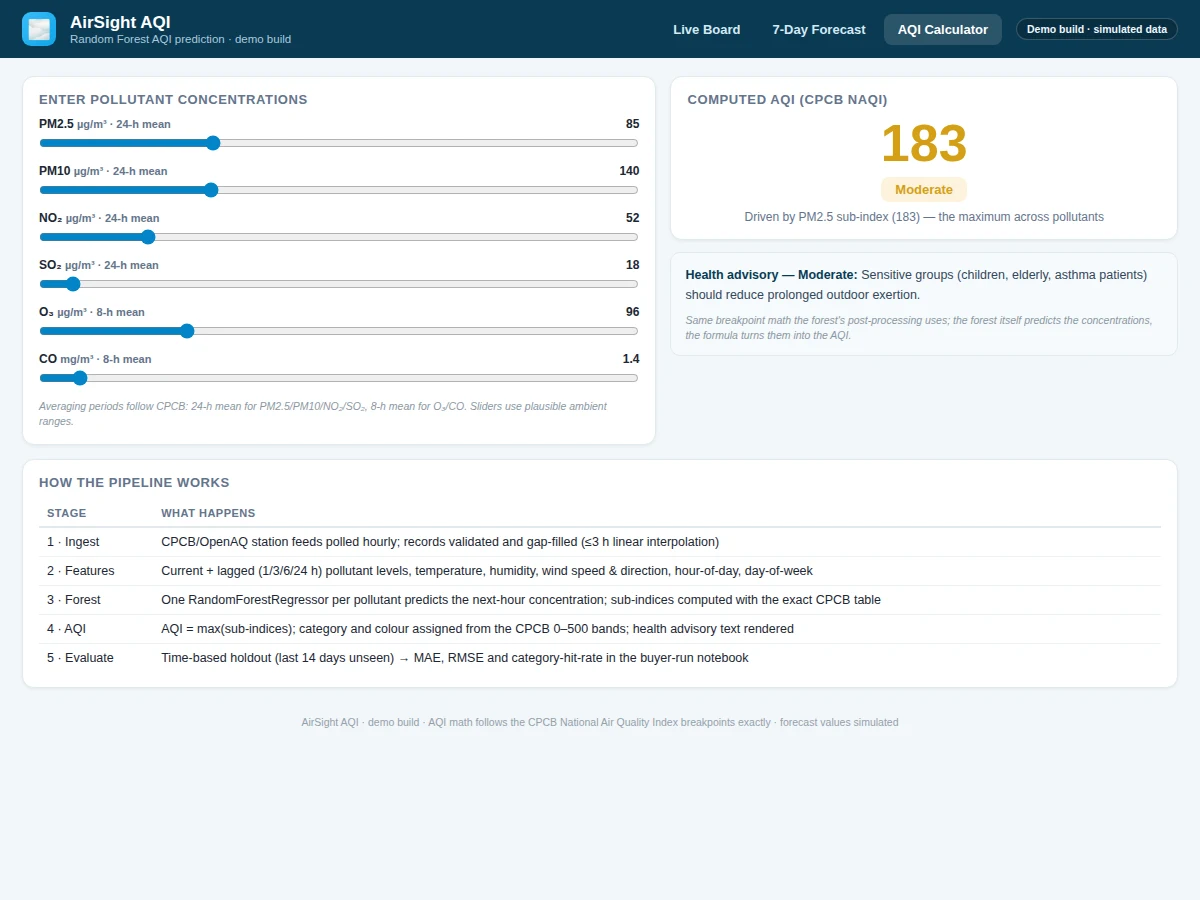
- Predicted concentrations pass through the exact CPCB breakpoint table: each pollutant gets a sub-index by interpolation, and the AQI is the maximum of the sub-indices.
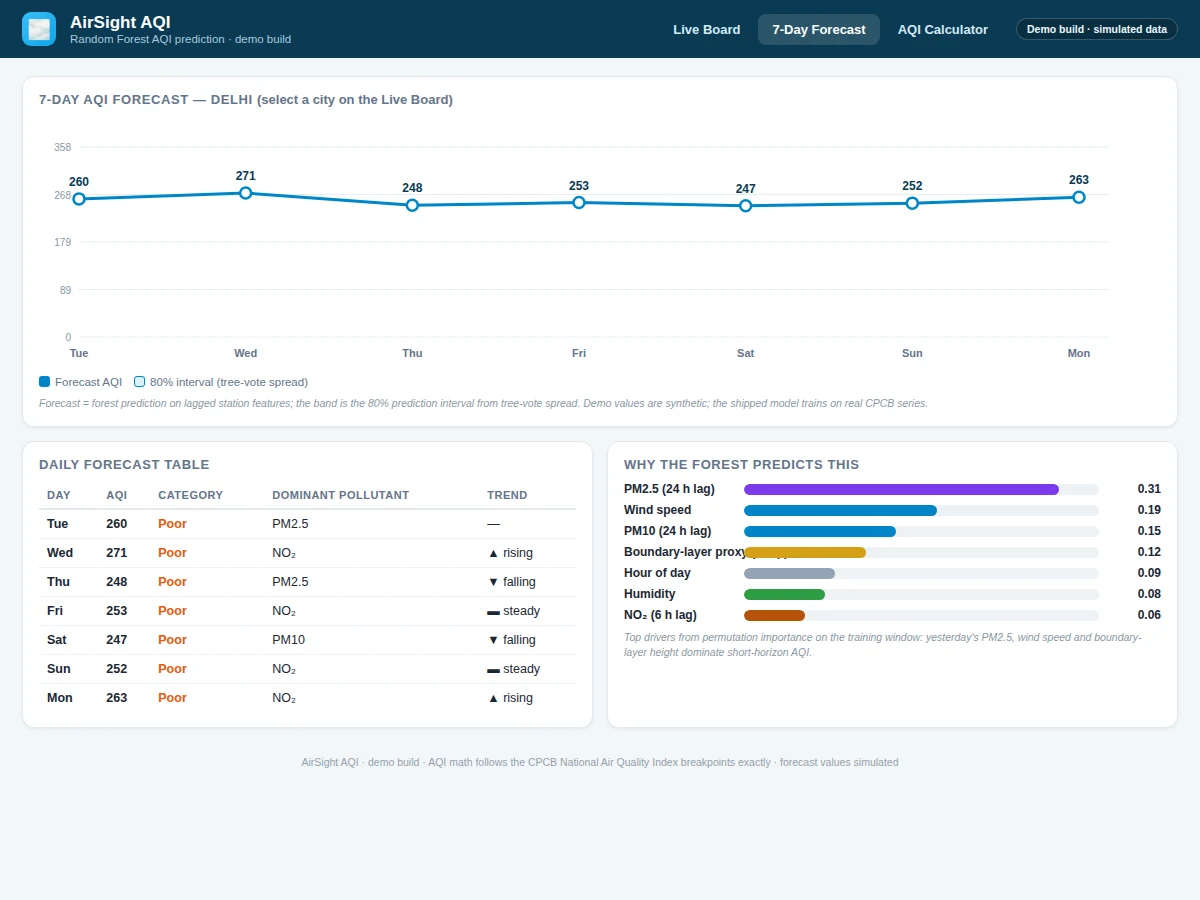
- The AQI maps to its category (Good → Severe), colour band and health-advisory text; the dashboard renders city cards, the hourly forecast with intervals, and the 7-day outlook.
- Evaluation uses a strict time-based holdout — the last 14 days are never seen in training — and the notebook reports per-pollutant MAE/RMSE plus how often the predicted AQI category matches the actual one.
Tech stack:
- Python 3.10, scikit-learn (RandomForestRegressor, metrics)
- pandas, NumPy (time-series wrangling, lag features)
- requests (scheduled CPCB/OpenAQ feed polling)
- Matplotlib, Seaborn (forecast-vs-actual, error analysis)
- Jupyter notebook (buyer-run training and evaluation)
- Flask demo app (live board, outlook, AQI calculator)
| Parameter | Value |
|---|---|
| Model | RandomForestRegressor × 6 (one per pollutant), 200 trees each |
| Task | Regression on concentrations → deterministic AQI via CPCB formula |
| Data | CPCB + OpenAQ public station records (hourly) |
| Features | Lagged pollutants (1/3/6/24 h), temperature, humidity, wind, hour, weekday |
| AQI math | Exact CPCB NAQI breakpoint interpolation; AQI = max sub-index |
| Validation | Time-based holdout (last 14 days unseen); MAE, RMSE, category-hit-rate |
| Horizon | Next 24 hours hourly; 7-day indicative outlook |
| Input | Station feed (auto) or manual concentrations in the calculator |
| Output | AQI 0–500, category, dominant pollutant, health advisory |
| Refresh | Design target ≤60 min poll cadence (feed dependent) |
Project features
- [Hourly station ingestion] Polls public CPCB/OpenAQ feeds on a schedule, validates every record against per-pollutant ranges, and interpolates only short gaps (≤3 h); longer gaps are flagged, never fabricated.
- [Lagged + meteorological features] Current and 1/3/6/24-hour lagged pollutant levels plus temperature, humidity, wind speed and direction, hour-of-day and day-of-week feed every prediction.
- [One forest per pollutant] A dedicated RandomForestRegressor (200 trees) predicts the next-hour concentration of PM2.5, PM10, NO₂, SO₂, O₃ and CO, since each pollutant disperses differently.
- [Exact CPCB NAQI computation] Sub-indices by linear interpolation between official breakpoints, AQI as the maximum sub-index, category and colour from the 0–500 bands — the same math the board itself uses.
- [Live board + 7-day outlook] City cards with dominant pollutant, an hourly next-day forecast with tree-vote prediction intervals, and a 7-day trend view.
- [AQI calculator] Enter pollutant concentrations manually and watch the identical breakpoint formula produce the AQI, category and health advisory — ideal for viva demonstrations.
- [Time-based holdout evaluation] The notebook trains on past weeks and tests on the most recent 14 days, reporting MAE, RMSE per pollutant and category-hit-rate for the final AQI.
What is included
- Complete source code (ingestion, features, training, AQI math, dashboard)
- Jupyter training and evaluation notebook (buyer-run: train, time-holdout, metrics, plots)
- Serialized per-pollutant forest models from the reference training run
- Project report PDF (background, CPCB methodology, evaluation, limitations)
- PPT presentation for final review
- Viva Q&A preparation document (lag features, breakpoint math, time-based validation)
- Setup guide (environment, data access, scheduler, running the demo)
Limitations & prerequisites
- Forecast skill decays with horizon: next-hour predictions are strong, but the multi-day outlook is indicative — the report shows this decay curve honestly.
- Episodes absent from training data (dust storms, intense stubble-burning weeks) are out-of-distribution events; the system flags them rather than pretending confidence.
- Station coverage is uneven — forecasts exist only where public stations report; the system does not invent data for unmonitored areas.
- The AQI formula implementation is exact, but it is only as current as the CPCB breakpoint table it encodes; any future CPCB revision needs a table update.
- This is an advisory and academic prototype, not an official forecasting service; health advisories follow CPCB wording and do not replace medical advice.
Frequently Asked Questions
Which data source is used?
Public station records from the Central Pollution Control Board (cpcb.nic.in) and the OpenAQ archive. Both are genuinely public; the notebook documents access and the ingestion scheduler polls them hourly.
Is the AQI calculation the real CPCB formula?
Yes. Sub-indices are computed by linear interpolation between the official CPCB breakpoint concentrations, and the AQI is the maximum sub-index — the demo's calculator runs this exact math so you can verify it by hand.
Why one model per pollutant instead of one model?
PM2.5, ozone and CO disperse and react differently; a single model would force one set of splits to fit six different physical behaviours. Per-pollutant forests are standard practice here.
Is the accuracy guaranteed?
No. The notebook evaluates on a strict time-based holdout (the most recent 14 days, never trained on) and reports MAE, RMSE and category-hit-rate from your own run — those measured numbers go in the report.
Can I add my city?
Yes, if CPCB or OpenAQ publishes a station for it — add the station ID to the ingestion config and retrain; the dashboard picks up new cities automatically.
Does it need internet?
Yes for the live feed — the forecaster polls station data hourly. Training on downloaded archives and the AQI calculator work fully offline. Suitable for B.E./B.Tech final-year projects in Computer Science, AI/ML and Data Science.
Components & software requirements
- Python 3.10, scikit-learn (RandomForestRegressor, metrics)
- pandas, NumPy (time-series wrangling, lag features)
- requests (scheduled CPCB/OpenAQ feed polling)
- Matplotlib, Seaborn (forecast-vs-actual, error analysis)
- Jupyter notebook (buyer-run training and evaluation)
- Flask demo app (live board, outlook, AQI calculator)
Delivery information
Built-to-order project. Delivery timeline is shared after order confirmation based on current queue.
Support terms
Complete documentation, setup guide, and viva preparation included. Support for setup and explanation provided.