
More project photos (3)
The problem
Turn your college's placement chaos into a chatbot that actually knows the answers. The RAG-Based AI Placement Assistant (built as the PlaceMate app) is a retrieval-augmented generation chatbot for college placement cells: instead of a generic LLM that hallucinates policy details, PlaceMate uploads your real documents — placement policies, past company visit archives, eligibility criteria, FAQs — chunks and embeds them into a vector database, and answers every student query with cited sources pulled from your own data. This is the standout 2026 final-year project: RAG is the hottest LLM architecture in the industry right now, and no Indian final-year project seller has productized a placement-cell RAG chatbot yet. You get a working LangChain pipeline, a clean Streamlit interface, and citations on every answer — exactly the kind of demonstrable, viva-proof AI system that wins top grades.
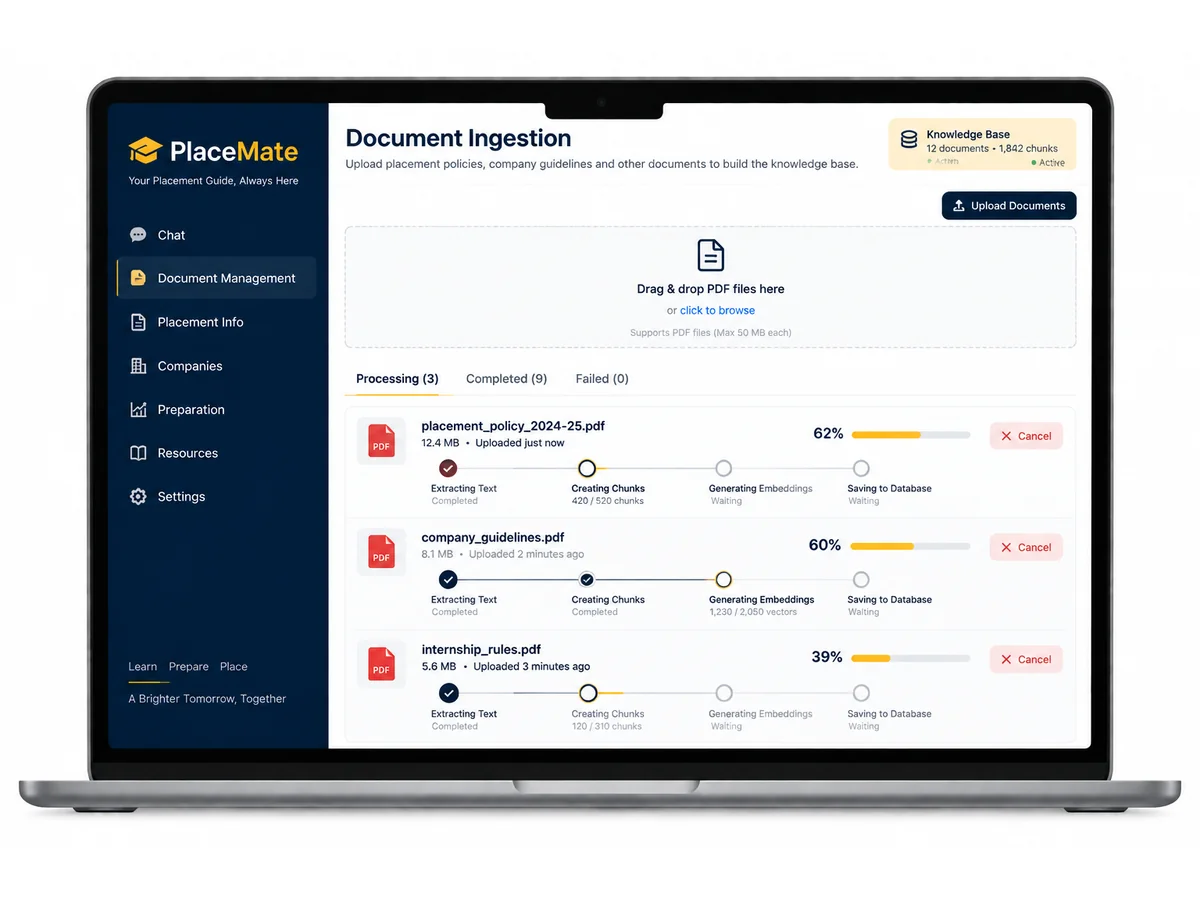
Uploads placement policies, company archives, and FAQ documents through the admin panel.
Follow the working sequence
How it works
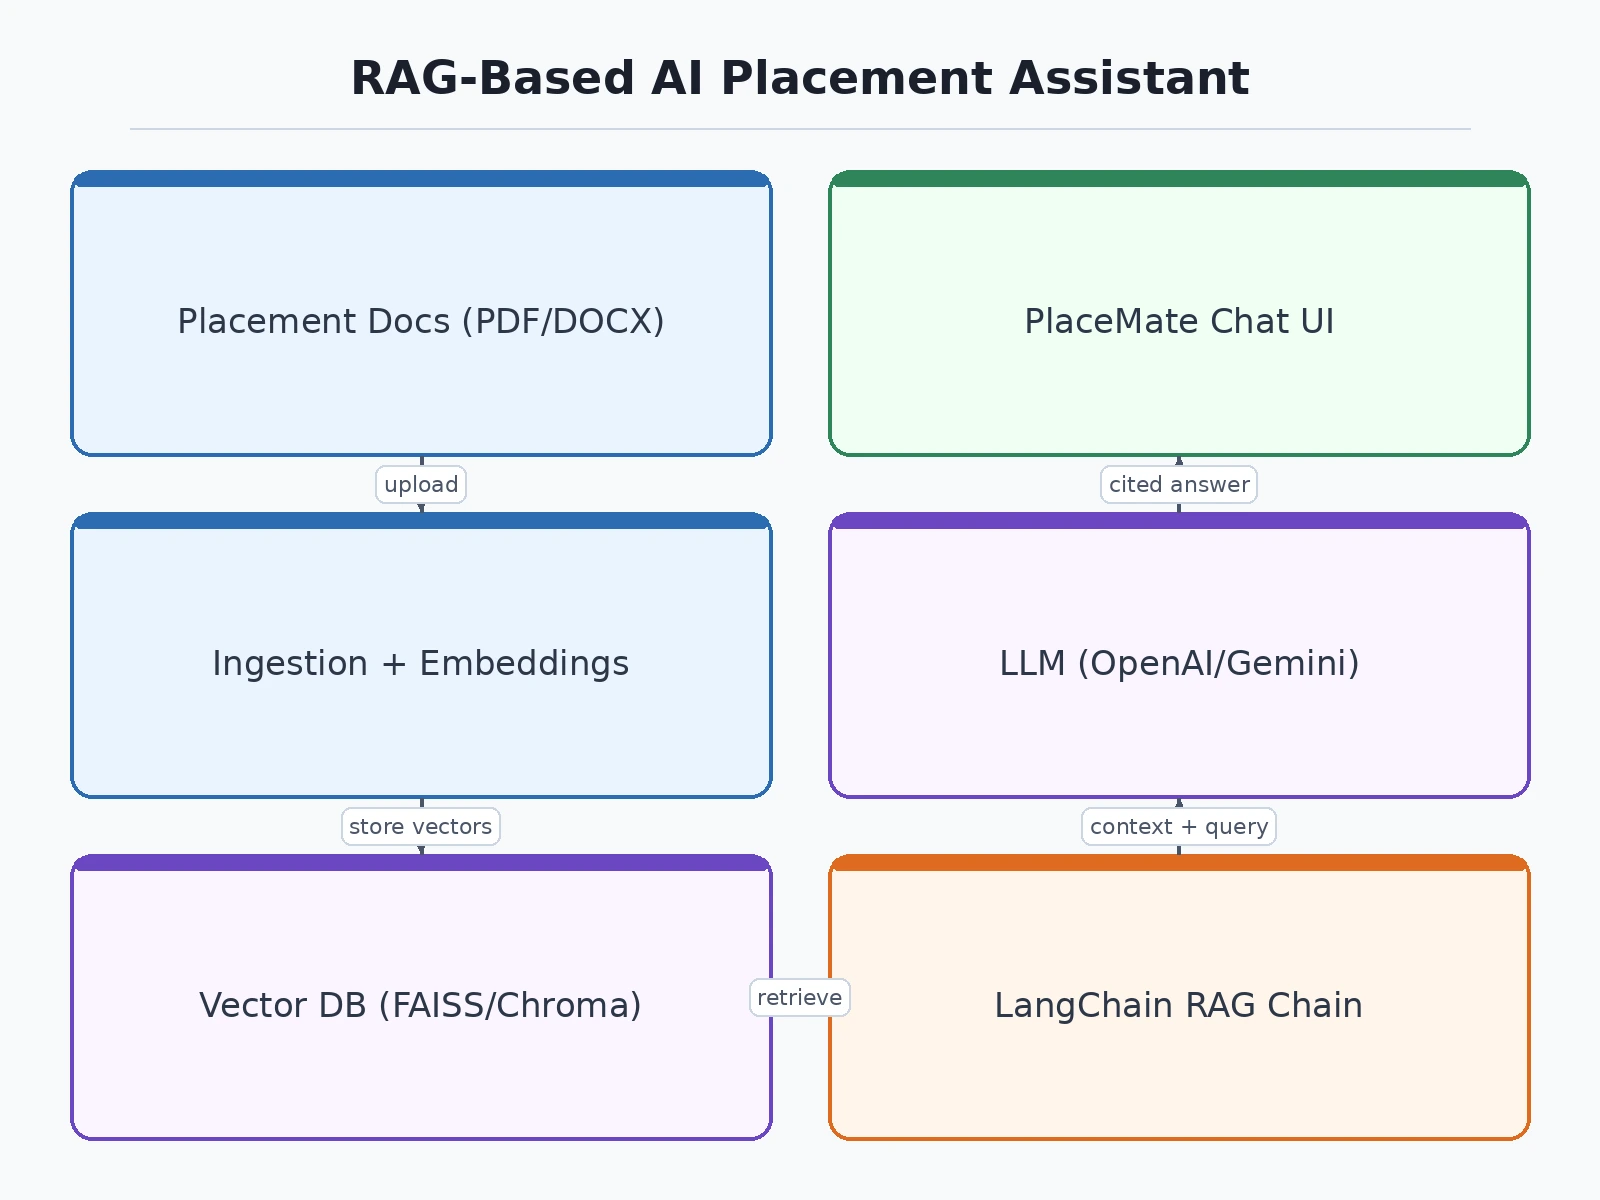
- The placement cell uploads documents (policies, company archives, FAQs) through the PlaceMate admin panel
- The ingestion pipeline cleans the text, splits it into chunks, generates embeddings and stores them in the vector database (FAISS/Chroma)
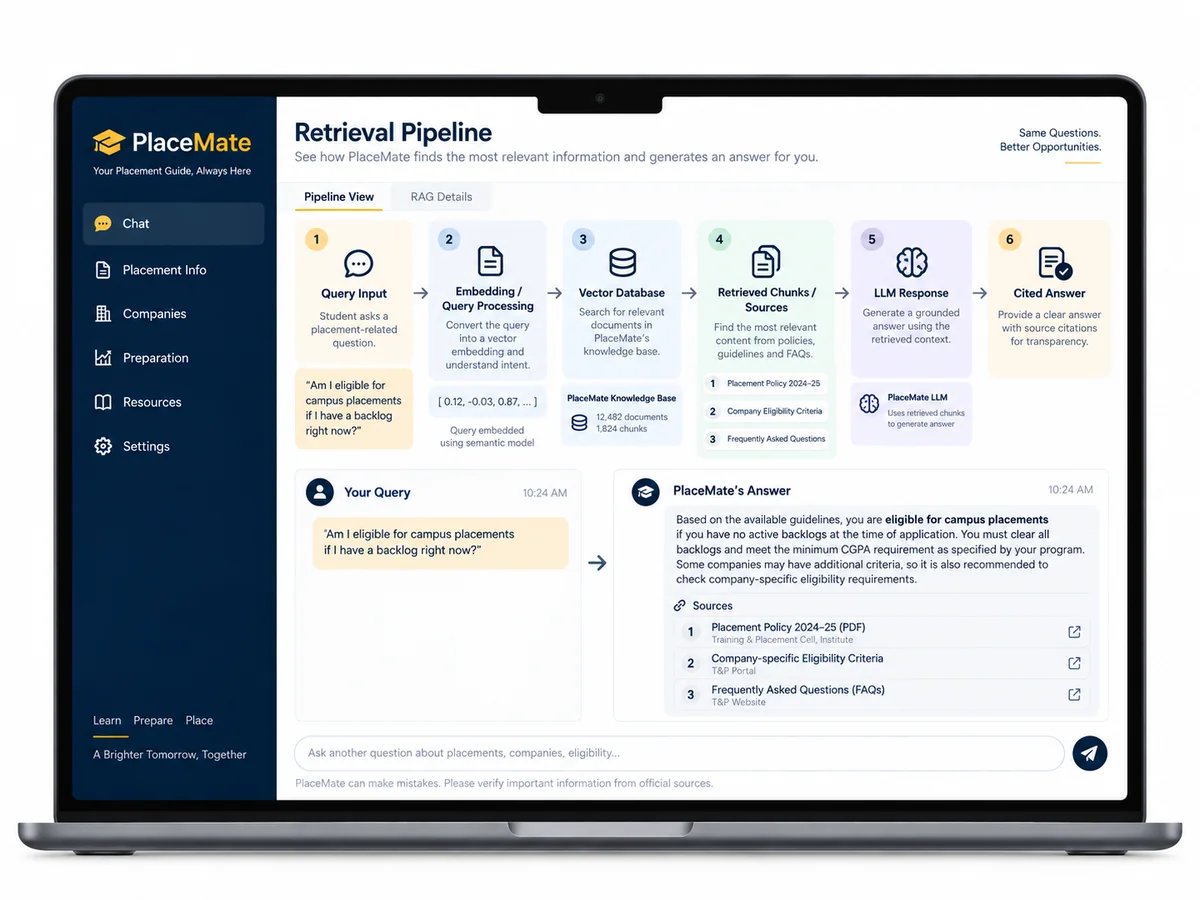
- A student asks a question in the PlaceMate chat interface — e.g. "What is the eligibility criteria for the TCS drive?"
- LangChain retrieves the most relevant chunks from the vector store and passes them to the LLM as grounded context
- The LLM generates an answer strictly from the retrieved documents, with citations pointing to the exact source
- Chat history is maintained so follow-up questions like "and what's the package for it?" resolve to the right company
Project features
- Document ingestion pipeline — upload PDFs, DOCX files and webpages (placement policies, company archives, FAQ sheets) into the PlaceMate knowledge base
- RAG chatbot with cited answers — every response includes the source documents and page references it was retrieved from
- LangChain orchestration — modular chains for ingestion, retrieval and generation, easy to explain in your viva
- Vector database retrieval (FAISS/Chroma) — semantic search over embeddings, not keyword matching
- Pluggable LLM backends — works with OpenAI-compatible and Gemini-compatible LLM APIs, swappable in one config line
- Placement-cell tuned UI — PlaceMate Streamlit app with chat history, source viewer and admin upload panel
- Hallucination control — answers constrained to retrieved context; the bot says "not found in documents" instead of inventing policy
- Conversation memory — follow-up questions resolve correctly using chat history context
What is included
- Complete PlaceMate source code (ingestion pipeline + RAG chain + Streamlit app)
- Ready-to-run setup with requirements file and configuration guide
- Sample placement documents dataset for demo and testing
- Detailed project report PDF (synopsis, architecture, implementation, testing, results)
- Presentation PPT for your final demo
- Viva Q&A set covering RAG, LangChain, embeddings, vector databases and LLM concepts
- Setup and demo support until your submission
Advantages
- RAG chatbot with cited answers — every response includes the source documents and page references it was retrieved from.
- Document ingestion pipeline for PDFs, DOCX files and webpages (placement policies, company archives, FAQ sheets).
- LangChain orchestration — modular chains for ingestion, retrieval and generation that are easy to explain in a viva.
- Vector-database retrieval (FAISS/Chroma) using semantic search over embeddings, not keyword matching.
- Pluggable LLM backends — OpenAI-compatible and Gemini-compatible APIs, swappable in one config line.
- Hallucination control — answers are constrained to retrieved context, and the bot says 'not found in documents' instead of inventing policy.
Disadvantages
- Answer quality depends on the quality and completeness of the uploaded documents — garbage in, garbage out.
- LLM API calls require an API key and internet access, and a small per-query cost may apply on paid tiers.
- Very large document collections (tens of thousands of pages) may need FAISS tuning for retrieval speed.
- The bot cannot answer questions outside the uploaded documents — it is intentionally constrained to retrieved context.
- The Streamlit app is designed for demo and departmental use, not high-concurrency production traffic.
Limitations & prerequisites
- Answer quality depends on the quality and completeness of the uploaded documents — garbage in, garbage out
- LLM API calls require an API key and internet access (OpenAI-compatible or Gemini-compatible); a small per-query cost may apply on paid tiers
- Very large document collections (tens of thousands of pages) may need FAISS tuning for retrieval speed
- The bot cannot answer questions outside the uploaded documents — it is intentionally constrained to retrieved context
- Streamlit app is designed for demo and departmental use, not high-concurrency production traffic
Components & software requirements
- Python
- LangChain (chains, document loaders, text splitters)
- Vector database: FAISS / Chroma
- Embeddings model for chunk indexing
- OpenAI-compatible / Gemini-compatible LLM APIs
- Streamlit web app (PlaceMate interface)
- Report PDF + PPT included
Download free synopsis (PDF)
Enter your name and WhatsApp number — the synopsis PDF downloads immediately. We may send occasional project updates on WhatsApp; no spam.