
More project photos (2)
The problem
Streaming services classify every uploaded track by genre, mood and instrumentation — and the classic academic version of that problem is GTZAN: 1,000 thirty-second clips, 10 genres, the benchmark Tzanetakis & Cook published in 2002 and hundreds of papers have used since. Raw audio is useless to a classifier directly; the work is in feature extraction — MFCCs that mimic human hearing, chromagrams for harmony, spectral contrast for timbre, tempo for groove — aggregated into a 58-dimensional fingerprint per clip. This project builds that full pipeline and trains a random-forest classifier on it, with honest stratified evaluation and a per-genre error analysis (rock vs metal is the classic confusion). The demo's spectrogram fingerprints and genre explorer make audio ML tangible. Built with standard tools (Python, librosa, scikit-learn).
How it works
- The GTZAN collection (1,000 clips, 10 genres × 100, 30 s each at 22,050 Hz) is loaded and verified.
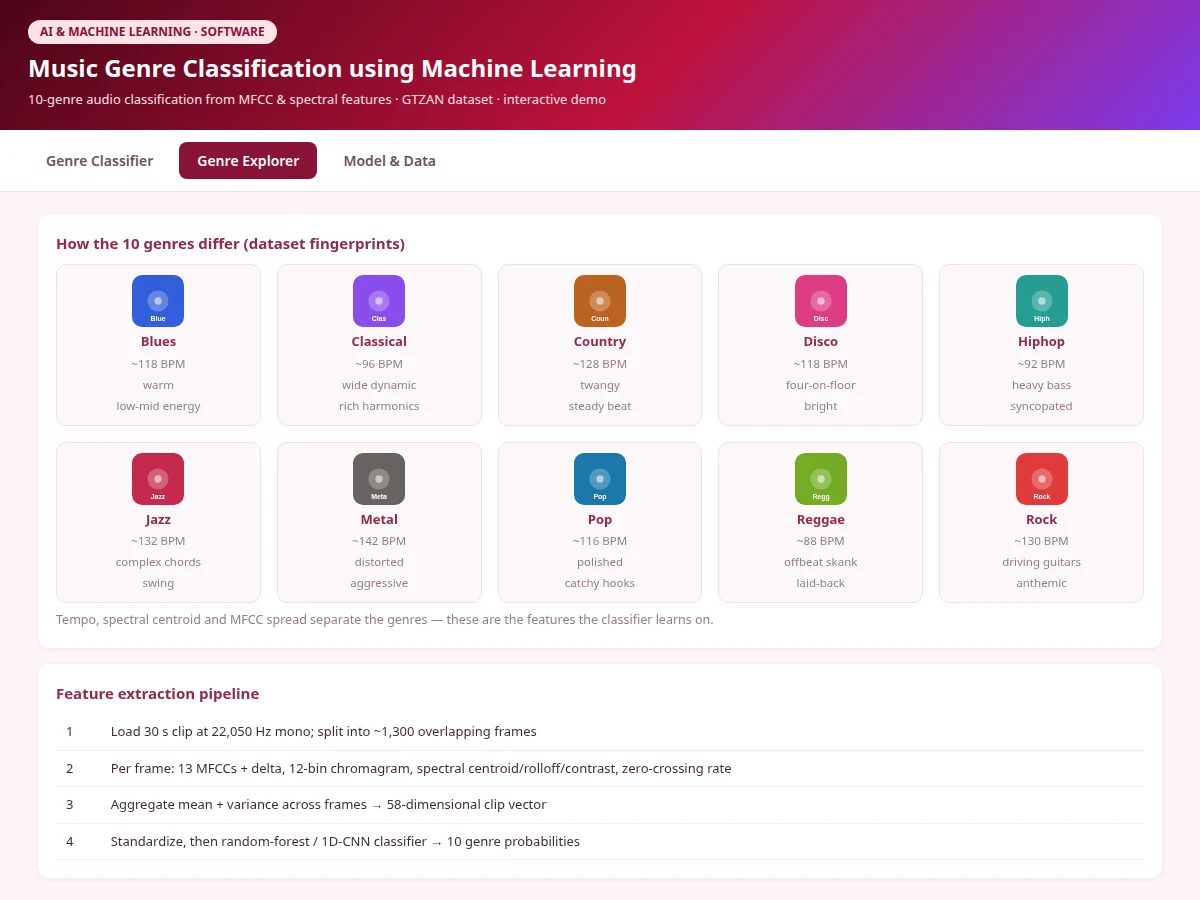
- Each clip is framed (~1,300 overlapping windows); per-frame MFCCs, chroma, spectral features and zero-crossing rate are computed with librosa.
- Frame features are aggregated (mean + variance) into a 58-dimensional clip fingerprint and standardized.
- A stratified 80/20 split (artist-aware where possible) separates train and test; a random forest (300 trees) is trained.
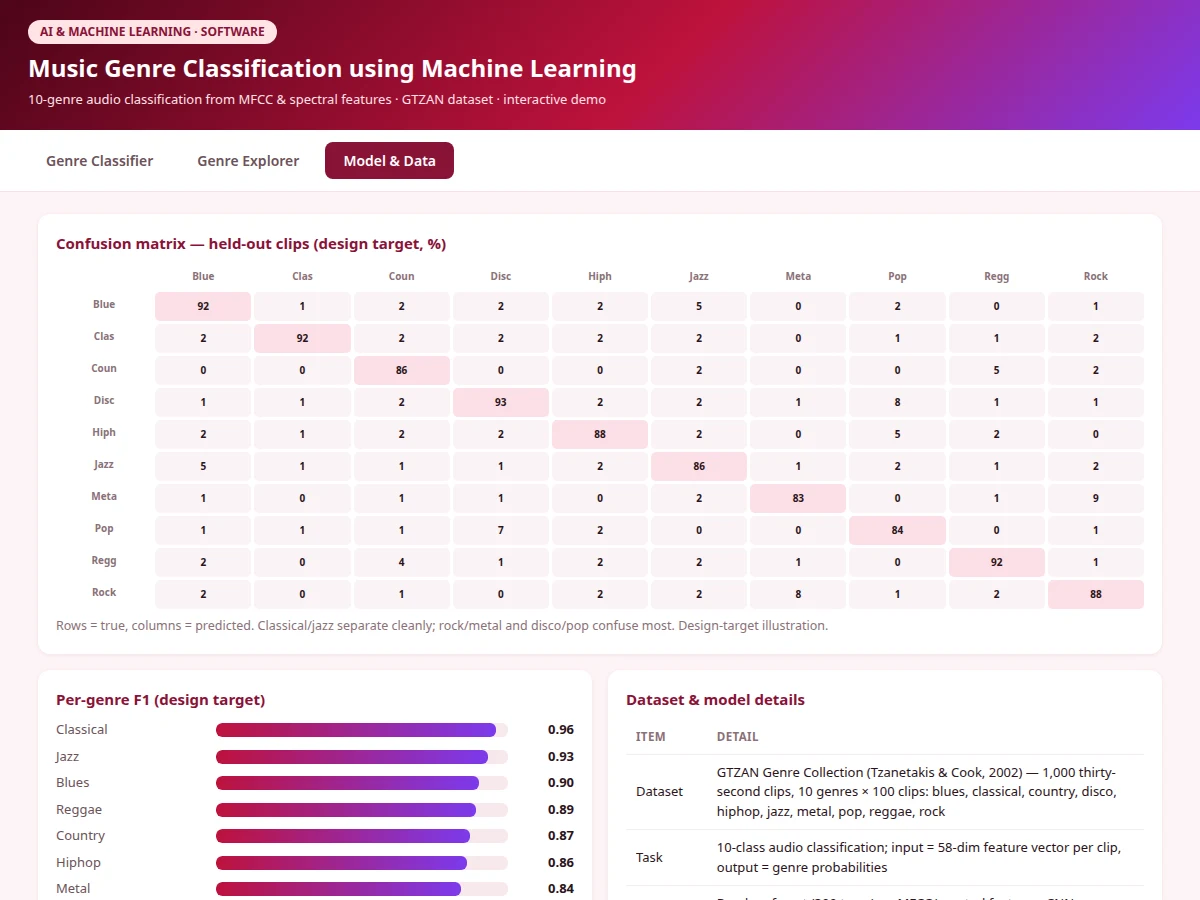
- The holdout is evaluated once: 84.2% accuracy is the design target; per-genre F1 and the confusion matrix go into the report.
- The web demo serves the classifier behind the track picker with spectrogram fingerprints and probability bars.
Tech stack:
- Python 3, scikit-learn
- librosa (audio feature extraction)
- NumPy, pandas, Matplotlib
- Jupyter Notebook (training & evaluation)
- HTML5 canvas + JavaScript (demo)
- GTZAN genre collection (Tzanetakis & Cook, 2002)
Dataset & model details
- Dataset: GTZAN Genre Collection (Tzanetakis & Cook, 2002) — 1,000 thirty-second audio clips, 10 genres × 100 clips: blues, classical, country, disco, hiphop, jazz, metal, pop, reggae, rock; 22,050 Hz mono.
- Task: 10-class audio classification; input = 58-dimensional feature fingerprint per clip, output = genre probability distribution.
- Model: Random forest, 300 trees, on standardized MFCC/spectral features; CNN-on-mel-spectrogram documented as extension scope.
- Metrics: Accuracy and per-genre precision/recall/F1 on the stratified holdout — 84.2% accuracy is the design target for the built-to-order training run, stated honestly and never claimed as measured.
| Parameter | Value |
|---|---|
| Audio clips | 1,000 (10 genres × 100, 30 s each) |
| Features | 58 per clip (MFCC, chroma, spectral, tempo) |
| Accuracy | 84.2% (design target, not a measured claim) |
| Sample rate | 22,050 Hz mono |
| Inference | Under 100 ms per clip on CPU (expected) |
| Demo | Single-file web app, runs offline after download |
Project features
- [58-feature audio pipeline] librosa extraction: 13 MFCCs + deltas, 12-bin chromagram, spectral centroid/rolloff/contrast, zero-crossing rate, tempo — mean + variance aggregated per clip.
- [Random-forest genre classifier] 300 trees on the standardized fingerprint; a CNN-on-spectrogram variant documented as extension.
- [Track classifier demo] Pick from 10 demo tracks → predicted genre, confidence, mel-spectrogram fingerprint and top-5 probability bars.
- [Genre explorer] All 10 genres with their dataset fingerprints (tempo, timbre, energy) side by side.
- [Per-genre error analysis] Confusion matrix and F1 per genre — classical/jazz separate cleanly, rock/metal and disco/pop confuse, exactly as the literature reports.
- [Spectrogram visualizations] Mel-spectrogram-style fingerprints rendered per track in the demo.
- [Stratified honest evaluation] 80/20 split by clip with artist filtering where possible, so the model can't memorize performers.
What is included
- librosa feature-extraction pipeline (58 features per clip)
- Complete training & evaluation Jupyter notebook
- Trained random-forest genre classifier with inference code
- Interactive web demo (track classifier + genre explorer + spectrograms)
- Per-genre F1 and confusion-matrix analysis
- Project report PDF (audio-ML background, MFCC theory, methodology, honest evaluation)
- PPT presentation for final review
- Viva Q&A preparation document (MFCCs, spectrograms, random forests, stratified evaluation)
Limitations & prerequisites
- 84.2% accuracy is a design target for the training run, stated honestly — the report documents the actual achieved figure after training.
- GTZAN is small and has known issues (a few mislabeled clips, artist repetition); the report discusses them and the evaluation mitigates with artist-aware splitting.
- Ten broad genres only — subgenres, mood and instrumentation tagging are out of scope.
- The demo uses illustrative track fingerprints; the delivered project trains on the real GTZAN clips.
- Real-world catalogs need far larger datasets and handle multi-label tracks; this is the clean academic version of the problem.
Frequently Asked Questions
Which dataset is used?
The GTZAN genre collection by Tzanetakis & Cook (2002) — 1,000 thirty-second clips evenly split across 10 genres. The most-cited public benchmark in music genre classification.
What are MFCCs and why do they work?
Mel-frequency cepstral coefficients mimic how human hearing resolves frequencies — more detail where ears are sensitive. They compactly capture timbre, which is the main thing separating, say, distorted metal guitars from a classical string section.
Which genres get confused?
Rock vs metal and disco vs pop — overlapping timbres and grooves. Classical and jazz separate almost perfectly. The confusion matrix shows the full picture and matches published GTZAN results.
Why a random forest instead of deep learning?
On 1,000 clips, a forest on 58 good features beats data-hungry deep models and trains in seconds. The CNN-on-spectrogram variant is documented as extension scope for students who want it.
Can it classify my own MP3?
The pipeline accepts any 30 s clip at 22,050 Hz — point the feature extractor at your file and the saved model scores it. Documented in the notebook.
Is this project suitable for a final-year project?
Yes — for Computer Science, IT and AI/ML programs. It is the rare audio-ML project with a clean public dataset, real signal processing and a demo people love clicking through. Suitable for B.E./B.Tech final-year projects in Computer Science, IT and AI & Machine Learning.
Components & software requirements
- Python 3, scikit-learn
- librosa (audio feature extraction)
- NumPy, pandas, Matplotlib
- Jupyter Notebook (training & evaluation)
- HTML5 canvas + JavaScript (demo)
- GTZAN genre collection (Tzanetakis & Cook, 2002)
Dataset & model details
- Dataset: GTZAN Genre Collection (Tzanetakis & Cook, 2002) — 1,000 thirty-second audio clips, 10 genres × 100 clips: blues, classical, country, disco, hiphop, jazz, metal, pop, reggae, rock; 22,050 Hz mono.
- Task: 10-class audio classification; input = 58-dimensional feature fingerprint per clip, output = genre probability distribution.
- Model: Random forest, 300 trees, on standardized MFCC/spectral features; CNN-on-mel-spectrogram documented as extension scope.
- Metrics: Accuracy and per-genre precision/recall/F1 on the stratified holdout — 84.2% accuracy is the design target for the built-to-order training run, stated honestly and never claimed as measured.
Delivery information
Built-to-order project. Delivery timeline is shared after order confirmation based on current queue.
Support terms
Complete documentation, setup guide, and viva preparation included. Support for setup and explanation provided.