
More project photos (2)
The problem
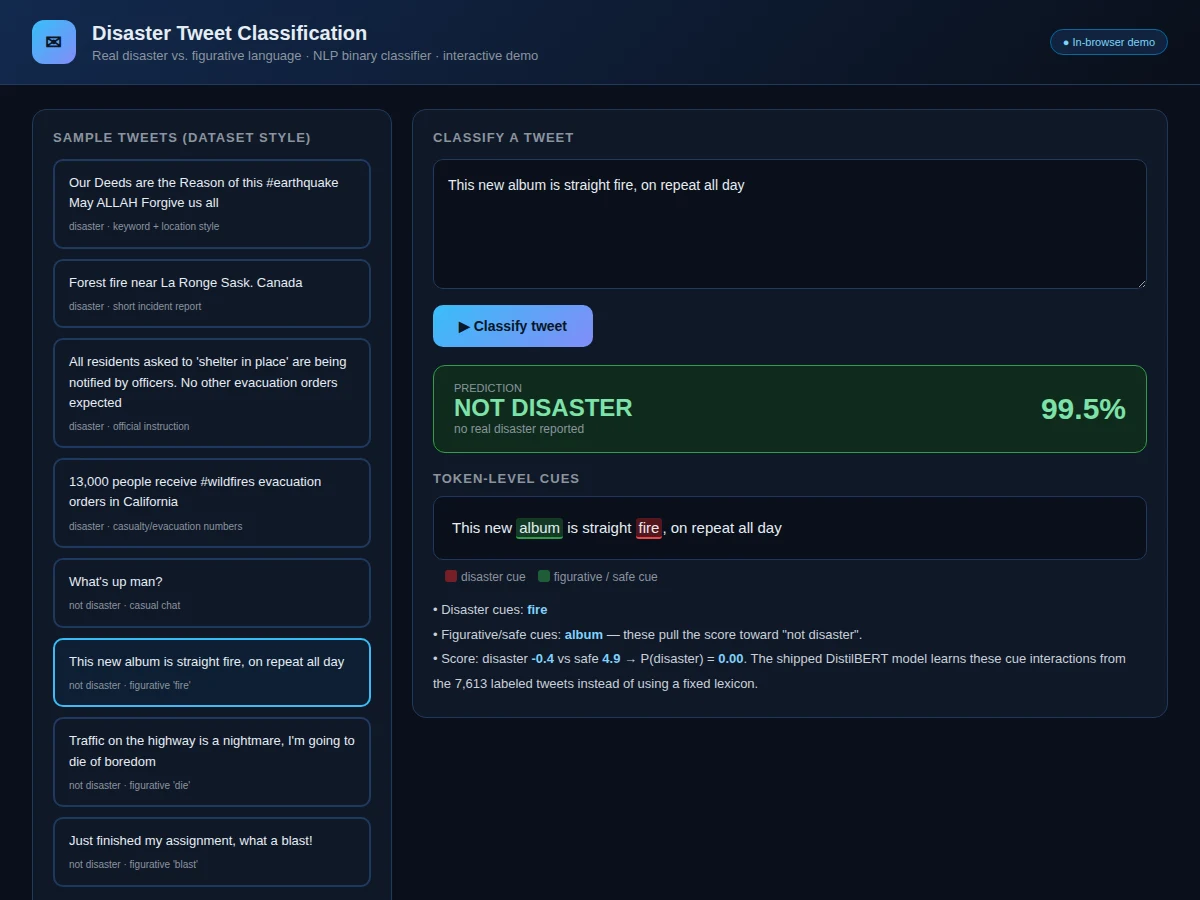
During a real disaster, Twitter fills with a mix of genuine incident reports ("forest fire near La Ronge, evacuations ordered") and figurative noise ("this traffic is a nightmare, I'm going to die"). Emergency responders want the first kind and not the second — and keyword matching fails spectacularly, because the word "fire" appears in both. This project solves it as a binary text-classification problem on the public "Natural Language Processing with Disaster Tweets" dataset: 7,613 human-labeled training tweets plus 3,263 test tweets. The project builds up in honest stages — a TF-IDF plus logistic-regression baseline that shows what linear models can and cannot do, then a fine-tuned DistilBERT that learns context ("fire" next to "album" vs next to "evacuation"), with the F1 improvement documented and explained for the viva.
How it works
- The 7,613 labeled tweets are cleaned (URLs, mentions and hashtags normalized; text lowercased) and split with stratification.
- The baseline converts tweets to TF-IDF vectors and trains logistic regression, establishing the score to beat.
- DistilBERT is fine-tuned for 3–4 epochs with a classification head, using the pretrained tokenizer and a learning-rate schedule.
- Both models are evaluated on the held-out set with accuracy, precision, recall and F1; the confusion matrix and error cases go into the report.
- Figurative-language probes ("this album is fire") verify the transformer handles what the baseline gets wrong.
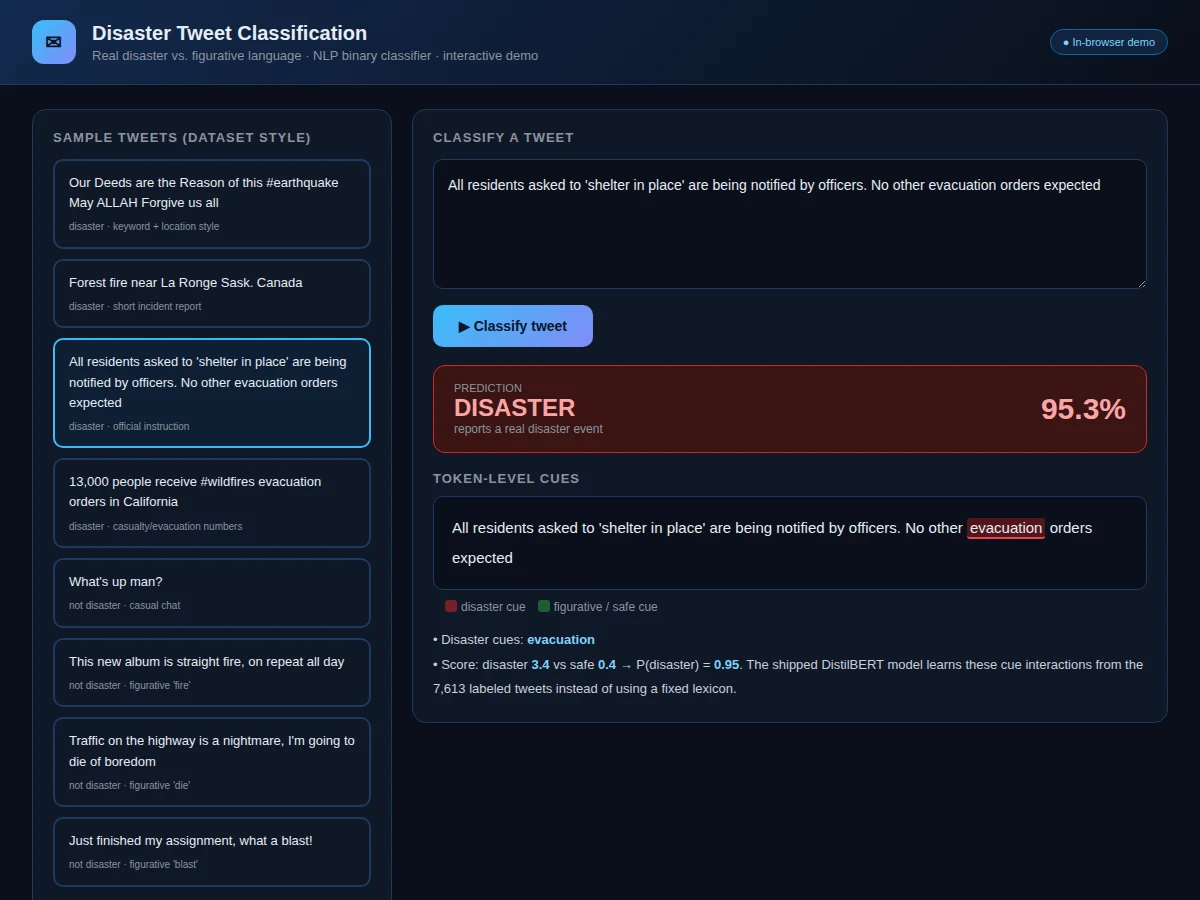
- In the demo, a typed tweet is tokenized and passed through the saved model; the app shows the verdict, confidence and token-level cue highlights.
Tech stack:
- Python 3, PyTorch, Hugging Face Transformers
- DistilBERT (fine-tuned)
- scikit-learn (TF-IDF baseline, metrics)
- Pandas, NumPy
- Jupyter Notebook (training & evaluation)
- HTML5 + JavaScript (live demo)
- Disaster-tweets dataset (Kaggle / Figure Eight labels)
Dataset & model details
- Dataset: "Natural Language Processing with Disaster Tweets" — 7,613 human-labeled training tweets and 3,263 test tweets, binary labels (real disaster vs not), labels collected via Figure Eight; released as a public Kaggle competition dataset.
- Task: Binary text classification; input = raw tweet text (≤ 280 chars), output = P(disaster).
- Model: DistilBERT-base fine-tuned with a sequence-classification head (3 epochs, AdamW, linear warmup); TF-IDF + logistic regression as the documented baseline.
- Metrics: F1 ≥ 0.79 on the held-out set (design target for the built-to-order fine-tuning run), plus precision/recall and accuracy. Competition-grade DistilBERT baselines report F1 around 0.79–0.82 in public notebooks; no figure is claimed as measured until the training run is executed for the order.
| Parameter | Value |
|---|---|
| Input | Raw tweet text (max 280 chars) |
| Output | P(disaster), binary decision |
| Training tweets | 7,613 labeled |
| F1 score | ≥ 0.79 (design target, not a measured claim) |
| Fine-tuning time | Approximately 15–30 min on a free GPU (expected) |
| Inference | Approximately 30 ms per tweet on CPU (expected) |
| Model files | Approximately 260 MB (DistilBERT weights + tokenizer, expected) |
| Demo | Single-file web app, runs offline after download |
Project features
- [DistilBERT fine-tuned classifier] Transformer model fine-tuned on the disaster-tweet labels, learning contextual cues instead of keyword lists.
- [Honest baseline first] TF-IDF + logistic regression baseline with error analysis, so the report shows exactly what the transformer buys over classical NLP.
- [Live tweet demo] Type or pick any tweet; the app returns disaster/not-disaster with confidence and highlights the words that drove the decision.
- [Figurative-language handling] The demo and report specifically address the hard cases — "fire," "blast," "die," "crash" used figuratively — with before/after examples.
- [Full training notebooks] Preprocessing, tokenization, baseline training, DistilBERT fine-tuning and evaluation in reproducible Jupyter notebooks.
- [Error analysis] Misclassified tweets reviewed and categorized (sarcasm, ambiguous reports, label noise) for a genuinely interesting report section.
- [Exported model] Fine-tuned weights plus tokenizer, so the demo classifies new tweets without retraining.
What is included
- Baseline + fine-tuning Jupyter notebooks
- Fine-tuned DistilBERT weights and tokenizer
- Live tweet-classification web demo
- Evaluation tables, confusion matrix, error-analysis section
- Project report PDF (background, NLP concepts, transformer theory, methodology, results)
- PPT presentation for final review
- Viva Q&A preparation document (tokenization, TF-IDF, attention, fine-tuning, F1 vs accuracy)
Limitations & prerequisites
- Tweets are short, noisy and English-only in this dataset — multilingual or long-form posts are out of scope.
- Sarcasm and genuinely ambiguous reports still fool the model; the error analysis documents these honestly.
- F1 ≥ 0.79 is a design target for the fine-tuning run, stated honestly — the report documents the actual achieved figure after training.
- The demo's in-browser classifier is a compact illustration of the pipeline; the full fine-tuned DistilBERT ships separately.
- Label noise exists in crowdsourced labels — noted as a bound on achievable performance.
Frequently Asked Questions
Which dataset is used and why?
The public disaster-tweets dataset — 7,613 human-labeled training tweets. It is the standard benchmark for this exact problem, and its labels capture the figurative-vs-real distinction that makes the task interesting.
Why is this harder than keyword matching?
Because "fire," "blast," "die" and "crash" appear in both real reports and figurative tweets. A keyword list cannot tell "forest fire, evacuations ordered" from "this album is fire" — the model must learn context.
What does DistilBERT add over the baseline?
The TF-IDF baseline sees word counts; DistilBERT sees word order and context, so "fire" next to "album" and "fire" next to "evacuation" get different representations. The report quantifies the F1 gap.
How does the demo highlight cues?
Disaster-leaning words and figurative/safe words are highlighted in different colors, with the running score shown — making the classifier's reasoning visible instead of a black box.
Can it monitor a live Twitter feed?
The classifier is the right core for it, but live ingestion needs API access, rate-limit handling and a streaming pipeline — listed as future scope, not included.
Is this project suitable for a final-year project?
Yes — for AI & Machine Learning, Computer Science and IT programs. It covers classical NLP, transformer fine-tuning, honest baseline comparison and a genuinely fun live demo. Suitable for B.E./B.Tech final-year projects in AI & Machine Learning, Computer Science and IT.
Components & software requirements
- Python 3, PyTorch, Hugging Face Transformers
- DistilBERT (fine-tuned)
- scikit-learn (TF-IDF baseline, metrics)
- Pandas, NumPy
- Jupyter Notebook (training & evaluation)
- HTML5 + JavaScript (live demo)
- Disaster-tweets dataset (Kaggle / Figure Eight labels)
Dataset & model details
- Dataset: "Natural Language Processing with Disaster Tweets" — 7,613 human-labeled training tweets and 3,263 test tweets, binary labels (real disaster vs not), labels collected via Figure Eight; released as a public Kaggle competition dataset.
- Task: Binary text classification; input = raw tweet text (≤ 280 chars), output = P(disaster).
- Model: DistilBERT-base fine-tuned with a sequence-classification head (3 epochs, AdamW, linear warmup); TF-IDF + logistic regression as the documented baseline.
- Metrics: F1 ≥ 0.79 on the held-out set (design target for the built-to-order fine-tuning run), plus precision/recall and accuracy. Competition-grade DistilBERT baselines report F1 around 0.79–0.82 in public notebooks; no figure is claimed as measured until the training run is executed for the order.
Delivery information
Built-to-order project. Delivery timeline is shared after order confirmation based on current queue.
Support terms
Complete documentation, setup guide, and viva preparation included. Support for setup and explanation provided.