
More project photos (5)
The problem
Sarcasm flips meaning — "Oh great, another Monday" means the opposite of what its words say — and it breaks every sentiment tool that reads text literally. Because sarcasm lives in context, contrast and exaggeration rather than in keywords, it is a classic hard problem for NLP and a genuinely interesting final-year build. This project tackles it with transfer learning: bert-base-uncased, pre-trained on massive English text, is fine-tuned on iSarcasmEval's author-annotated tweets, where the labels come from the tweet authors themselves rather than third-party guessers. The demo scores any pasted tweet and visualizes token attention so the verdict is explainable — the report can point at exactly which words the model treated as sarcasm cues, and the error analysis can discuss the cases sarcasm detection still gets wrong, such as world-knowledge jokes and deadpan delivery.
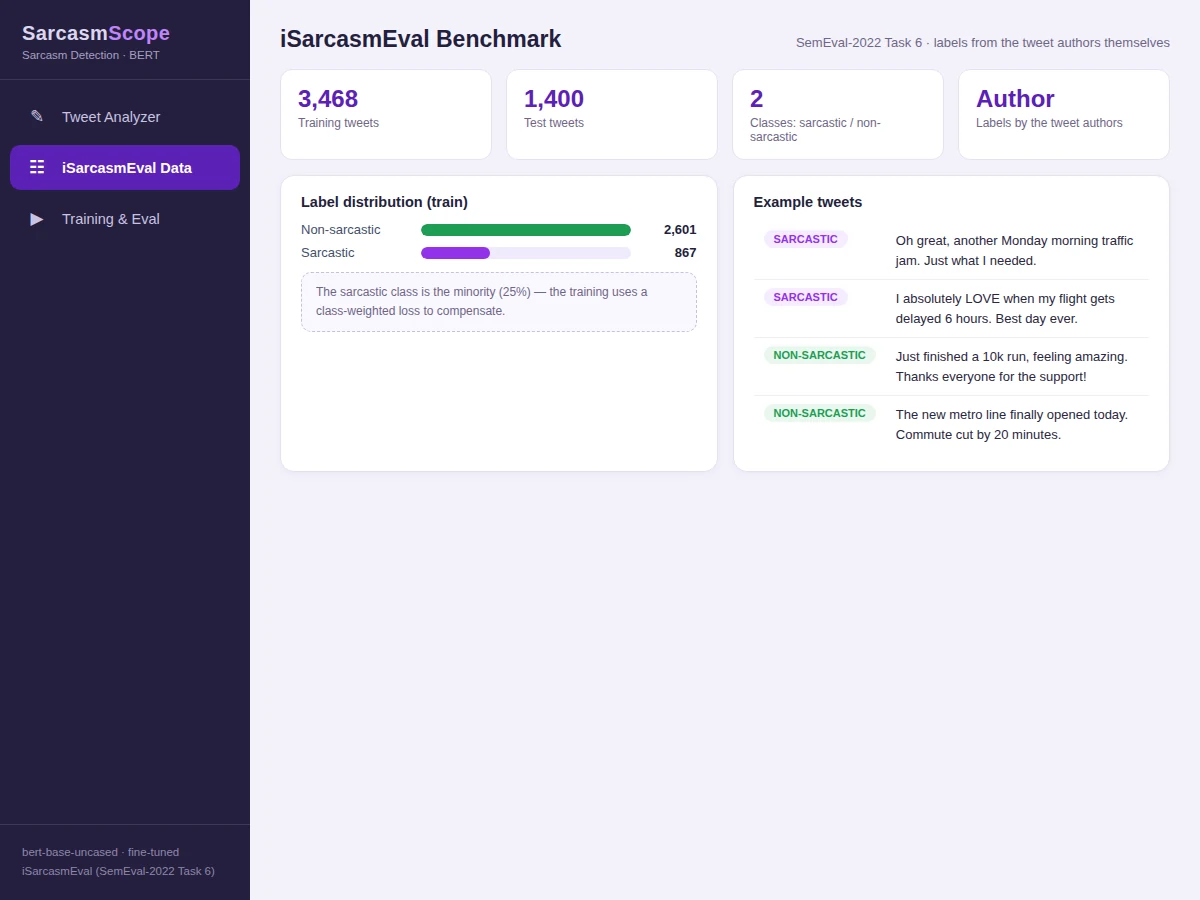
Author-annotated English tweets from iSarcasmEval (SemEval-2022 Task 6): 3,468 train / 1,400 test.
Follow the working sequence
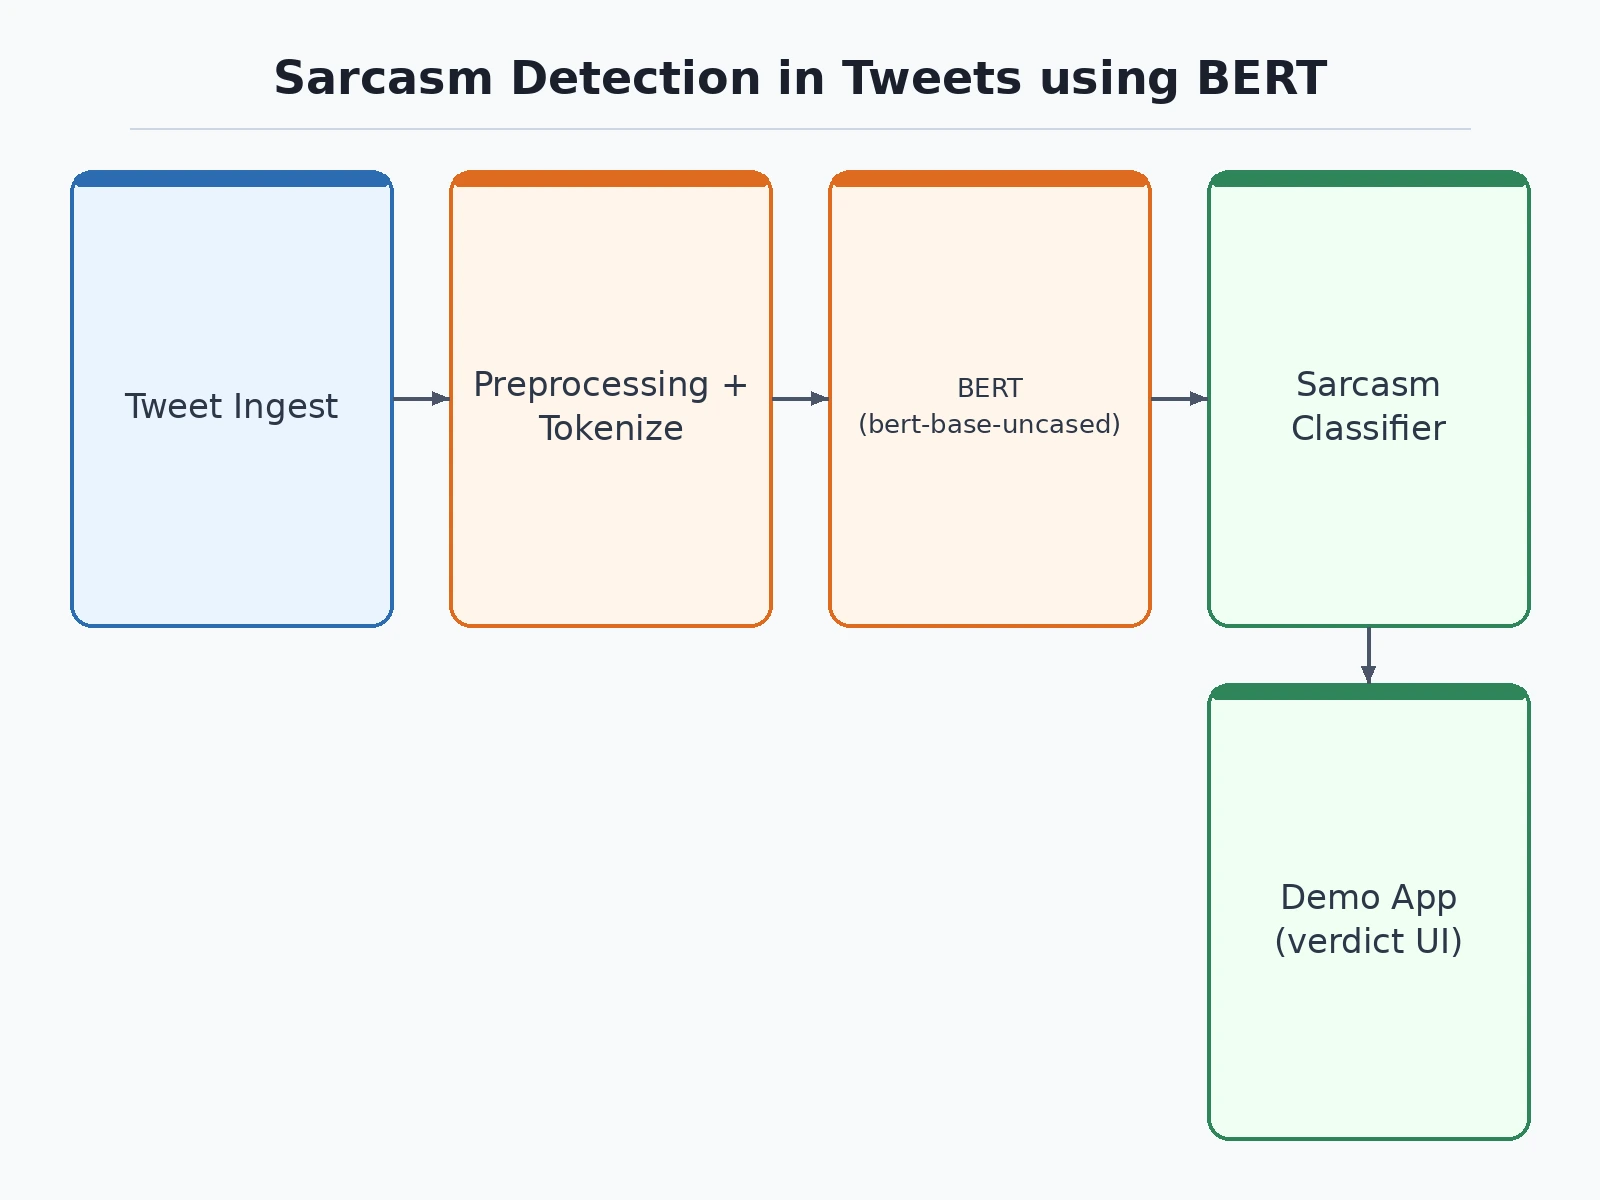
How it works
- iSarcasmEval tweets are WordPiece-tokenized (max 128 tokens); author-provided sarcastic/non-sarcastic labels are kept as the binary target.
- bert-base-uncased feeds its CLS embedding into a dropout + linear head; class weights in the cross-entropy loss compensate for the sarcastic-class minority.
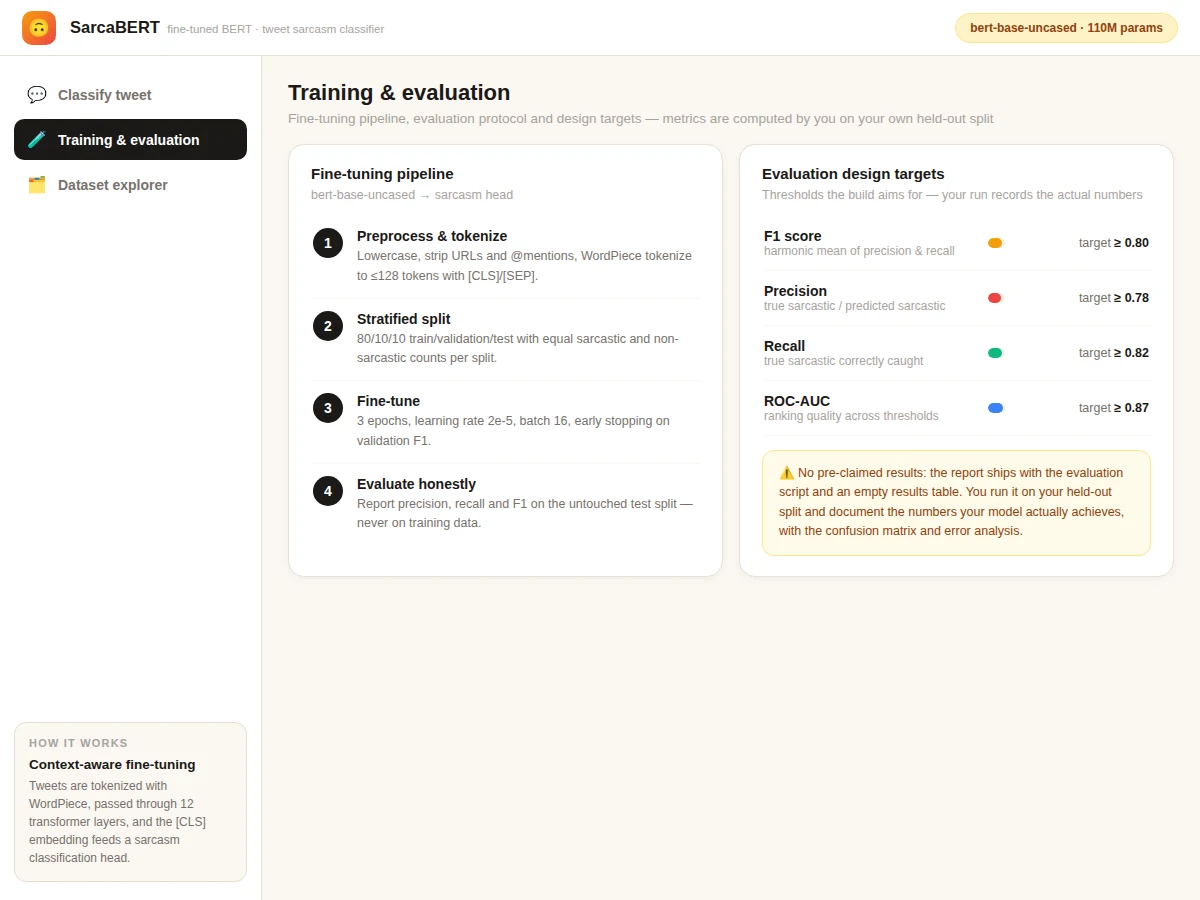
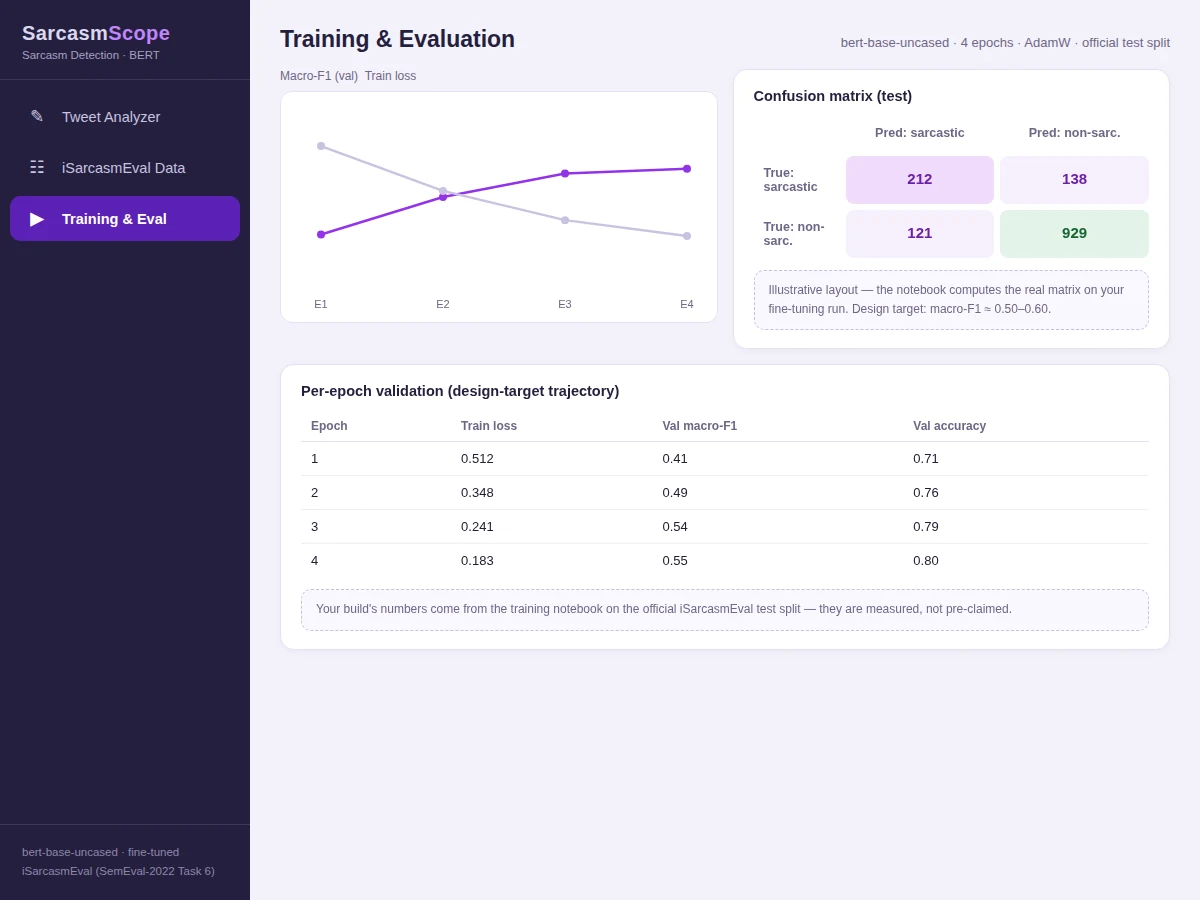
- The model is fine-tuned for about 4 epochs with AdamW; every epoch logs accuracy, precision, recall, macro-F1 and the confusion matrix on the validation split.
- At inference, the demo app tokenizes the pasted tweet, runs it through the fine-tuned model and renders the verdict with a confidence bar.
- Attention-based token influence scores color each word by how strongly it pushed the decision toward sarcastic or non-sarcastic.
- Batch mode reads a CSV of tweets and writes per-tweet verdicts and confidences to a report file.
Tech stack:
- Python 3.10, PyTorch, Hugging Face transformers (bert-base-uncased)
- scikit-learn (metrics, confusion matrix), NumPy, pandas
- Matplotlib (training curves, label distribution)
- Single-file HTML/CSS/JS demo app (analyzer, dataset explorer, training views)
- iSarcasmEval benchmark (SemEval-2022 Task 6, author-annotated tweets)
- Trained weights exported from the included fine-tuning run
| Parameter | Value |
|---|---|
| Model | bert-base-uncased + dropout/linear head (110M parameters) |
| Dataset | iSarcasmEval (SemEval-2022 Task 6): 3,468 train / 1,400 test English tweets |
| Labels | Sarcastic / non-sarcastic, annotated by the tweet authors |
| Input | English tweets, max 128 WordPiece tokens |
| Output | Sarcastic/non-sarcastic verdict, confidence score, token-attention highlights |
| Training | ~4 epochs, AdamW, linear warmup, class-weighted loss; design target macro-F1 ≈ 0.50–0.60 |
| Evaluation | Accuracy, precision, recall, macro-F1, confusion matrix — computed by the notebook on your build |
| Inference | CPU-friendly; a single tweet scores in well under a second |
Project features
- [Tweet analyzer] Paste any tweet and get a sarcastic/non-sarcastic verdict with a confidence bar; token-attention highlighting colors the words that most pushed the decision.
- [BERT fine-tuning pipeline] bert-base-uncased with a dropout + linear classification head, fine-tuned with AdamW and a linear warmup schedule; class-weighted loss counters the label imbalance; all hyperparameters exposed in the notebook.
- [Author-annotated data] Trains on iSarcasmEval (SemEval-2022 Task 6), where sarcasm labels come from the tweet authors themselves — the gold standard for this task.
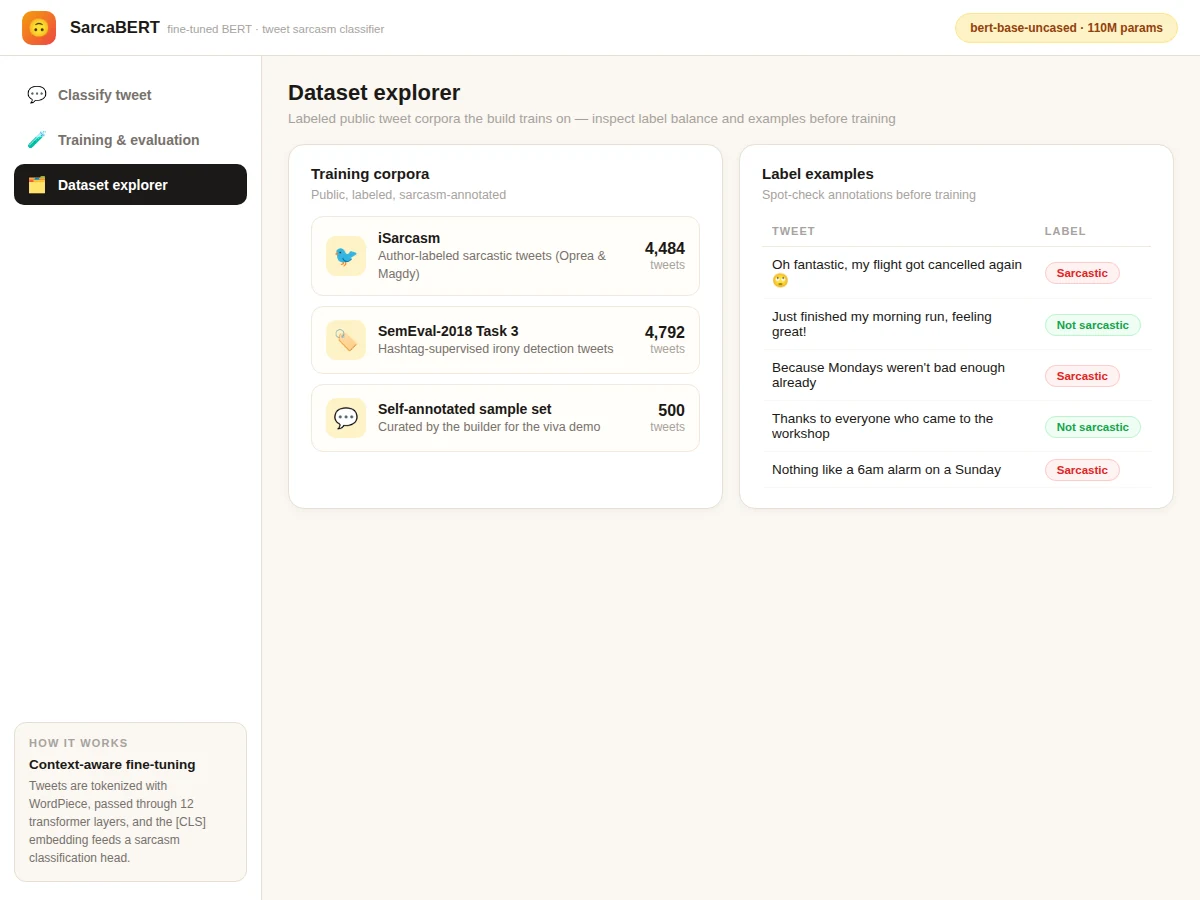
- [Dataset explorer view] Browse the iSarcasmEval label distribution, tweet-length stats and train/test splits inside the demo app, with real example tweets from each class.
- [Training-curve view] Per-epoch macro-F1 and train/validation loss plots that the notebook reproduces during the build.
- [Batch scoring mode] Score a CSV of tweets into a verdict report for larger-scale analysis.
- [Full evaluation logging] Accuracy, precision, recall, macro-F1 and the confusion matrix computed on the official iSarcasmEval test split — never pre-claimed.
What is included
- Complete source code (preprocessing, fine-tuning, attention extraction, inference, demo app)
- Jupyter training and evaluation notebook (buyer-run procedure: fine-tune, evaluate, inspect errors)
- Project report PDF (background, iSarcasmEval analysis, methodology, evaluation, error analysis)
- PPT presentation for final review
- Viva Q&A preparation document (transformers, attention, fine-tuning, class imbalance, evaluation metrics)
- Setup guide (environment, dataset download, training, running the demo)
Advantages
- Author-annotated benchmark data: trains on iSarcasmEval (SemEval-2022 Task 6), where sarcasm labels come from the tweet authors themselves, the gold standard for this task.
- Interpretable verdicts: the demo app returns a sarcastic/non-sarcastic verdict with a confidence bar and token-level attention highlighting that shows which words pushed the decision toward sarcasm.
- Principled training setup: bert-base-uncased with a dropout plus linear classification head, fine-tuned with AdamW and a linear warmup schedule, with class-weighted loss countering the label imbalance.
- Full evaluation logging: accuracy, precision, recall, macro-F1 and the confusion matrix computed on the official iSarcasmEval test split, never pre-claimed.
- Training-curve view: per-epoch macro-F1 and train/validation loss plots that the notebook reproduces during the build.
- Batch scoring mode: scores a CSV of tweets into a verdict report for larger-scale analysis.
Disadvantages
- The model detects sarcasm in short English tweets, the iSarcasmEval domain: sarcasm that needs world knowledge, cultural context or multi-turn conversation is outside its reach and it handles such cases poorly.
- A verdict is a statistical prediction, not a reading of intent: low-confidence outputs must be read as model uncertainty and passed to human review.
- Deadpan sarcasm with no lexical cues is systematically hard: the confusion matrix in the report documents the error patterns openly.
- Fine-tuning BERT needs a GPU (or long CPU patience): the notebook documents expected runtimes and a smaller-sample quick-run mode.
- Emojis and hashtags are kept as features, but heavily abbreviated or image-only tweets carry too little text to classify.
Limitations & prerequisites
- The model detects sarcasm in short English tweets — the iSarcasmEval domain. Sarcasm that needs world knowledge, cultural context or multi-turn conversation is outside its reach and it handles such cases poorly.
- A verdict is a statistical prediction, not a reading of intent: low-confidence outputs must be read as model uncertainty and passed to human review.
- Deadpan sarcasm with no lexical cues is systematically hard; the confusion matrix in the report documents the error patterns openly.
- Fine-tuning BERT needs a GPU (or long CPU patience) — the notebook documents expected runtimes and a smaller-sample quick-run mode.
- Emojis and hashtags are kept as features but heavily abbreviated or image-only tweets carry too little text to classify.
Frequently Asked Questions
Which dataset is used?
iSarcasmEval (SemEval-2022 Task 6): 3,468 training and 1,400 test English tweets whose sarcasm labels were provided by the tweet authors themselves — the most reliable labeling scheme available for this task.
Which model is used?
bert-base-uncased (110M parameters) with a dropout + linear classification head, fine-tuned with AdamW and a class-weighted loss to handle the sarcastic-class minority.
Is the accuracy guaranteed?
No. The design target is macro-F1 ≈ 0.50–0.60 on the iSarcasmEval test split — sarcasm is a genuinely hard task with modest ceiling scores even for published systems — and final performance is measured by the training notebook during your build.
Can it detect sarcasm in other languages or long posts?
Not reliably — training covers short English tweets only. Other languages, long-form text and image memes are outside the training distribution.
What are the main limitations?
English tweets only; world-knowledge and deadpan sarcasm are systematically hard; confidence is model uncertainty, not ground truth; fine-tuning needs a GPU for reasonable runtimes.
Is this project suitable for a final-year project?
Yes — for Computer Science, AI/ML and Data Science programs. It demonstrates transformers, transfer learning, attention-based explanation, class-imbalance handling and honest error analysis, all strong viva material. Suitable for B.E./B.Tech final-year projects in Computer Science, AI/ML and Data Science.
Components & software requirements
- Python 3.10, PyTorch, Hugging Face transformers (bert-base-uncased)
- scikit-learn (metrics, confusion matrix), NumPy, pandas
- Matplotlib (training curves, label distribution)
- Single-file HTML/CSS/JS demo app (analyzer, dataset explorer, training views)
- iSarcasmEval benchmark (SemEval-2022 Task 6, author-annotated tweets)
- Trained weights exported from the included fine-tuning run
Delivery information
Built-to-order project. Delivery timeline is shared after order confirmation based on current queue.
Support terms
Complete documentation, setup guide, and viva preparation included. Support for setup and explanation provided.
Download free synopsis (PDF)
Enter your name and WhatsApp number — the synopsis PDF downloads immediately. We may send occasional project updates on WhatsApp; no spam.