
More project photos (2)
The problem
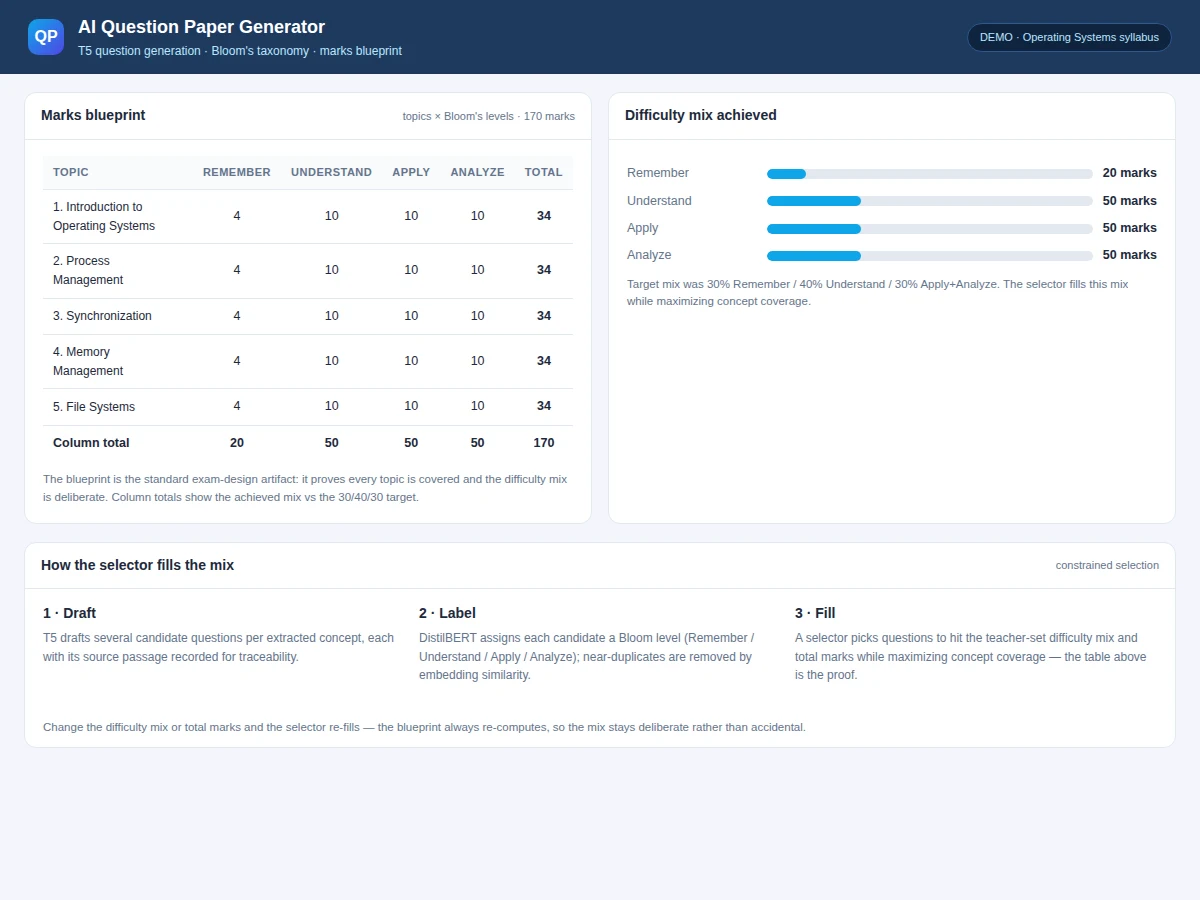
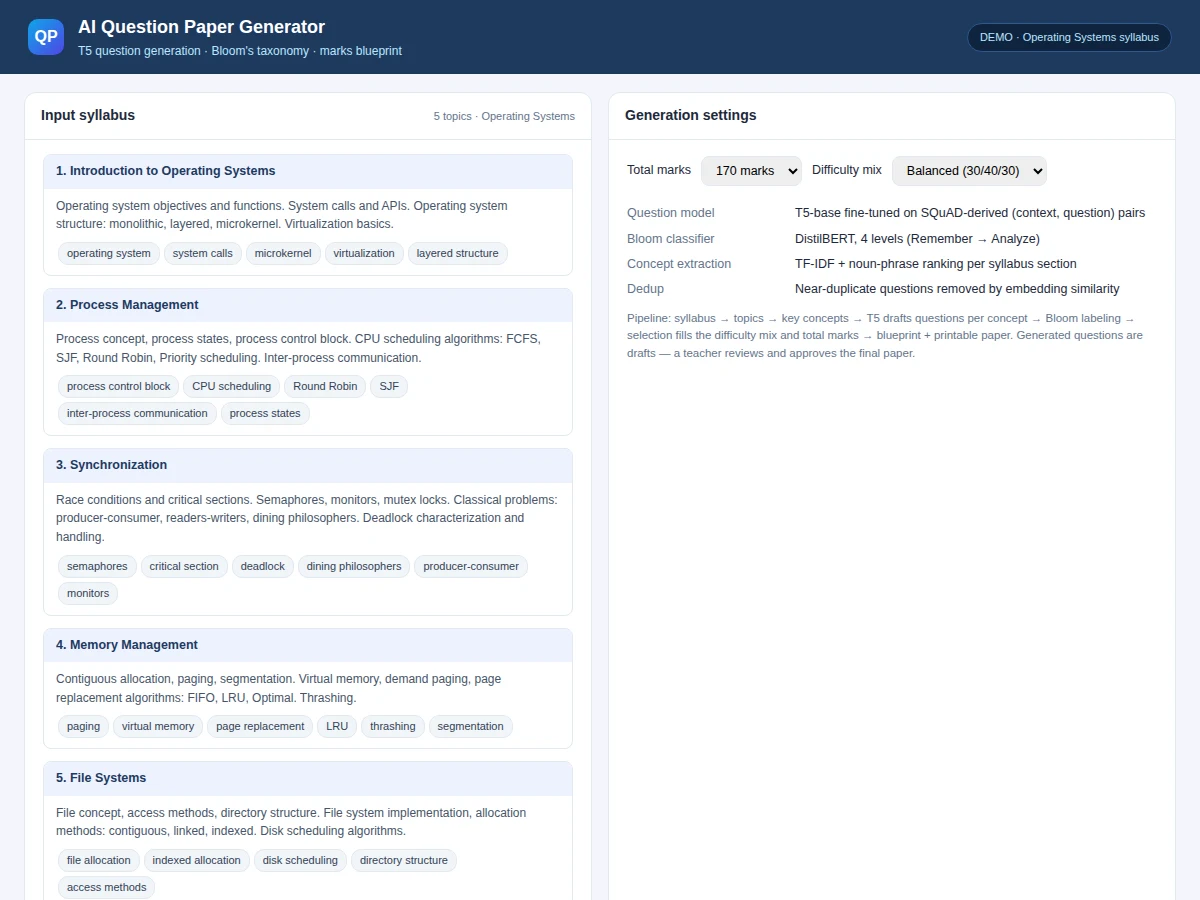
Setting a good question paper is slow, skilled work: the paper must cover the whole syllabus proportionally, mix recall with analysis-level questions, and avoid repeating last year's paper. Faculty do it by hand, and question banks go stale. This project automates the drafting stage — not the final judgment. Given syllabus text, a T5 question-generation model fine-tuned on SQuAD-derived (context, question) pairs drafts candidate questions from each syllabus section; a concept extractor ensures every key topic is covered; and a Bloom's-taxonomy classifier labels each question (remember, understand, apply, analyze) so the difficulty mix is deliberate. A blueprint table shows exactly how marks distribute across topics and cognitive levels, and the teacher edits the draft into the final paper. The demo generates a complete 70-mark paper from a sample operating-systems syllabus in seconds.
How it works
- Syllabus text is segmented into topics; a TF-IDF + noun-phrase extractor identifies the key concepts per topic.
- For each concept, the surrounding syllabus passage and the concept are fed to the fine-tuned T5 question-generation model, which drafts candidate questions.
- A Bloom's-level classifier (DistilBERT fine-tuned on labeled question data) labels each generated question's cognitive level.
- A selection stage picks questions to satisfy the teacher's difficulty mix and total marks while maximizing concept coverage and minimizing near-duplicates.
- The blueprint table is computed (marks per topic per Bloom's level) and the paper renders in printable format with sections and instructions.
- The demo evaluates generation quality with BLEU/METEOR against SQuAD references and shows a human-rated sample in the report.
Tech stack:
- Python 3.11, Hugging Face Transformers
- T5-base fine-tuned for question generation
- SQuAD 2.0 (Stanford, 100k+ QA pairs)
- DistilBERT (Bloom's-level classifier)
- scikit-learn (TF-IDF concept extraction, metrics)
- Flask + HTML/CSS/JS (demo)
- PyTorch (fine-tuning)
Dataset & model details
- Dataset: SQuAD 2.0 (Rajpurkar et al., Stanford, 2018) — 100,000+ question–answer pairs on Wikipedia articles, restructured into (context, question) pairs for question-generation training. Source: rajpurkar.github.io/SQuAD-explorer.
- Task: Question generation — input = syllabus passage + target concept, output = natural exam question; plus Bloom's-level classification of generated questions.
- Model: T5-base (220M parameters) fine-tuned on SQuAD-derived QG pairs; DistilBERT classifier for Bloom's taxonomy levels (4 classes).
- Metrics: BLEU/METEOR for generation quality against SQuAD references; Bloom's classifier accuracy on labeled questions — design targets reported after training.
| Parameter | Value |
|---|---|
| Training pairs | 100k+ (context, question) from SQuAD 2.0 |
| QG model | T5-base fine-tune, ~220M parameters |
| Bloom's levels | Remember / Understand / Apply / Analyze |
| Generation BLEU | Design target (reported after training) |
| Paper assembly | Under 10 s for a 70-mark paper on CPU (expected) |
| Demo | Single-file web app, preloaded OS syllabus |
Project features
- [T5 question generation] T5 fine-tuned on SQuAD-derived pairs drafts natural questions grounded in the provided syllabus text.
- [Concept coverage] Key concepts are extracted per syllabus section and every concept gets question coverage — no silent topic gaps.
- [Bloom's taxonomy labeling] Each question is classified into Remember / Understand / Apply / Analyze so the difficulty mix is measurable.
- [Marks blueprint] A blueprint table shows marks distributed across topics × cognitive levels, the standard exam-design artifact.
- [Difficulty mix control] The teacher sets the target mix (e.g. 30% recall, 40% understanding, 30% application/analysis) and the generator fills it.
- [Printable paper format] The draft renders as a clean, formatted exam paper with sections, marks, and general instructions.
- [Live web demo] Paste syllabus text or use the preloaded OS syllabus; the full paper generates instantly with its blueprint.
What is included
- Fine-tuned T5 question-generation model
- Concept extraction + Bloom's classification + blueprint pipeline source
- Web demo with preloaded operating-systems syllabus
- QG evaluation notebook (BLEU/METEOR, human-rated samples)
- Difficulty-mix configuration presets
- Project report PDF (background, question generation, Bloom's taxonomy, methodology, results)
- PPT presentation for final review
- Viva Q&A preparation document (T5, SQuAD, BLEU, Bloom's taxonomy)
Limitations & prerequisites
- Generated questions are drafts — a teacher must review, edit and approve the final paper; the project never claims exam-ready output without human review.
- BLEU/METEOR are design targets until training executes; the report records achieved figures plus human ratings.
- The model generates from the given syllabus text only; it cannot invent questions about topics not present in the input.
- Numerical/problem-style questions (derivations, circuit analysis) are weaker than theory questions — documented in the limitations.
- Demo syllabus is operating systems; other subjects work the same way but need their text pasted in.
Frequently Asked Questions
Which dataset trains the question generator?
SQuAD 2.0 — over 100,000 question–answer pairs on Wikipedia articles, restructured so the model learns to write questions from passages. It is the standard public dataset for question generation.
Does it just copy sentences as questions?
No — T5 generates fresh question phrasing from the passage and target concept, and a deduplication stage removes near-identical questions.
How does it control difficulty?
Every generated question is classified into a Bloom's taxonomy level, and the selector fills the teacher's chosen mix (e.g. 30% recall / 40% understanding / 30% higher-order).
What is the blueprint table?
The standard exam-design artifact: a grid of marks per syllabus topic per cognitive level, so coverage is verifiable at a glance.
Can teachers use the output directly?
As a draft, yes — the project is explicit that generated papers need human review and approval before any real exam use.
Is this project suitable for a final-year project?
Yes — for Computer Science, IT and AI/ML programs. It combines text generation, classification and a real exam-design workflow in one demonstrable system. Suitable for B.E./B.Tech final-year projects in Computer Science, IT and AI & Machine Learning.
Components & software requirements
- Python 3.11, Hugging Face Transformers
- T5-base fine-tuned for question generation
- SQuAD 2.0 (Stanford, 100k+ QA pairs)
- DistilBERT (Bloom's-level classifier)
- scikit-learn (TF-IDF concept extraction, metrics)
- Flask + HTML/CSS/JS (demo)
- PyTorch (fine-tuning)
Dataset & model details
- Dataset: SQuAD 2.0 (Rajpurkar et al., Stanford, 2018) — 100,000+ question–answer pairs on Wikipedia articles, restructured into (context, question) pairs for question-generation training. Source: rajpurkar.github.io/SQuAD-explorer.
- Task: Question generation — input = syllabus passage + target concept, output = natural exam question; plus Bloom's-level classification of generated questions.
- Model: T5-base (220M parameters) fine-tuned on SQuAD-derived QG pairs; DistilBERT classifier for Bloom's taxonomy levels (4 classes).
- Metrics: BLEU/METEOR for generation quality against SQuAD references; Bloom's classifier accuracy on labeled questions — design targets reported after training.
Delivery information
Built-to-order project. Delivery timeline is shared after order confirmation based on current queue.
Support terms
Complete documentation, setup guide, and viva preparation included. Support for setup and explanation provided.